K-Means
- Rows
- One cluster each.
- Center
- A mean.
- Distance
- Euclidean.
Loading…
K-Means assigns each row to the nearest mean. Fuzzy C-Means keeps a membership for every row, with m=2.0, and the published scores use the hardened memberships.
Choose whether every row keeps a membership or joins the nearest mean.
This is a choice, not a measured winner.
Silhouette is within 0.01 on Iris Flowers, Wine (UCI wine recognition), and Customer Segments; Fuzzy C-Means Clustering agrees more with the held-out label on Iris Flowers and Customer Segments; Held-out agreement is within 0.01 on Wine (UCI wine recognition).
Do you need a membership for every row?
A membership, with the published scores taken from the hardened memberships.
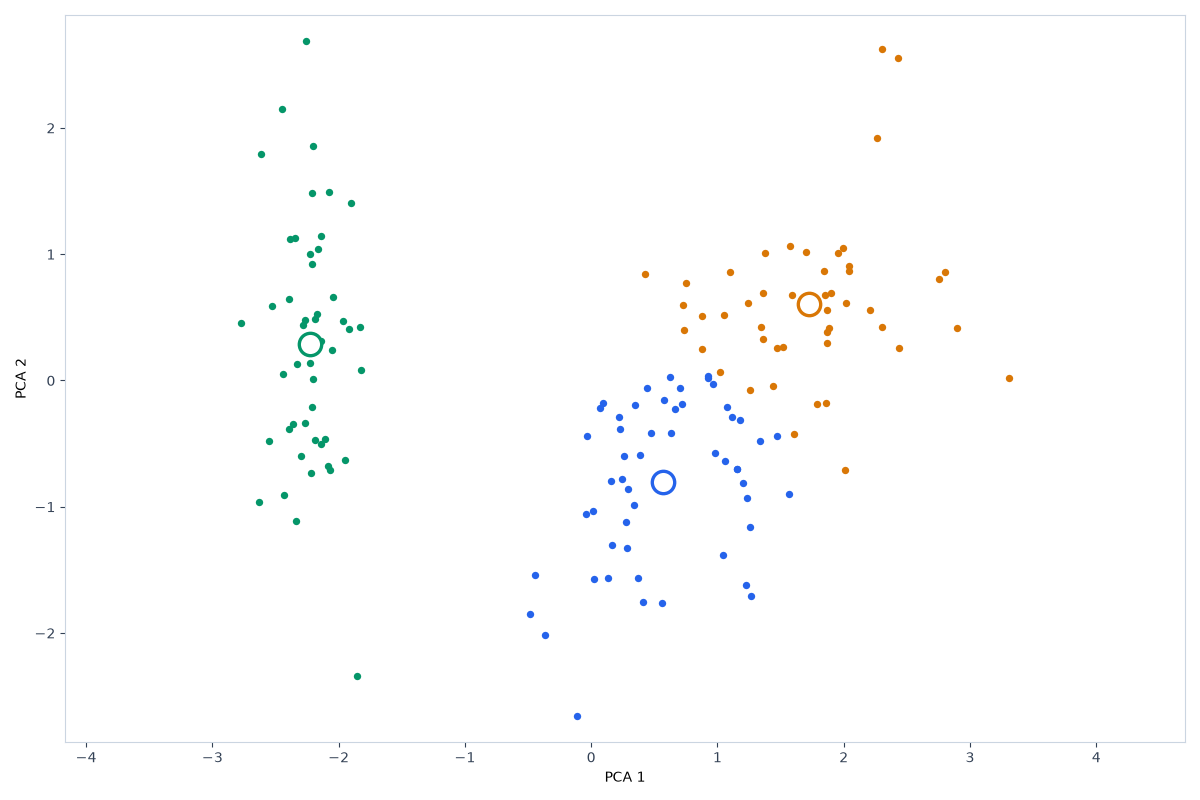
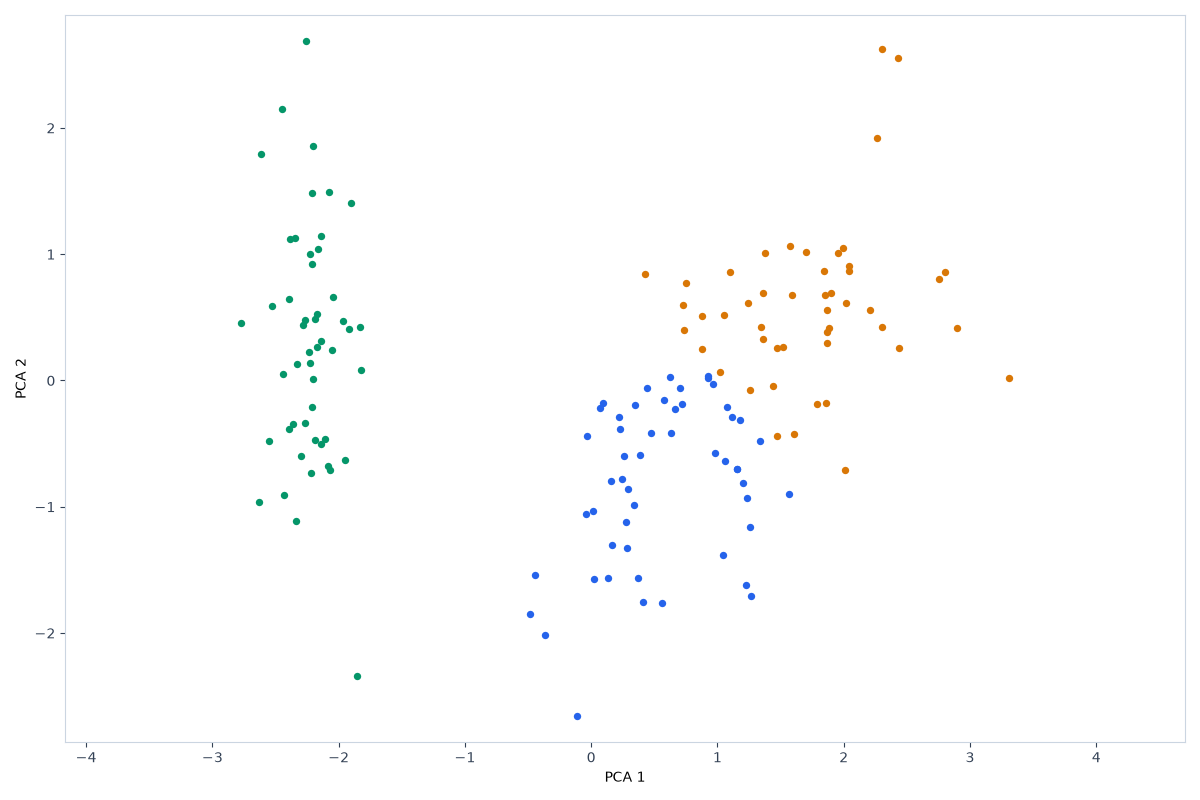
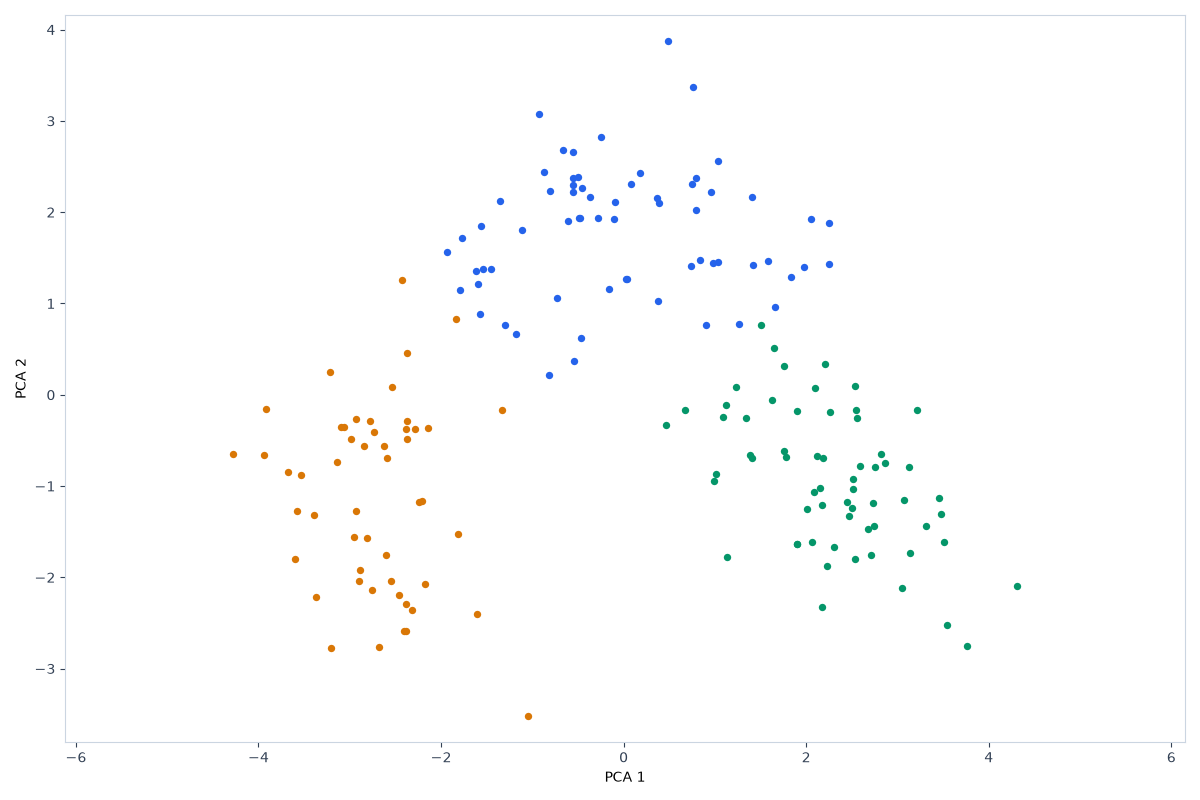
Fuzzy C-Means on Iris Flowers (150 rows and 4 features) keeps a membership for every row (m=2.0). The published scores use the hardened memberships: 3 clusters, silhouette 0.458, adjusted Rand 0.630. K-Means on the same scaled rows uses 3 means, silhouette 0.460, adjusted Rand 0.620. The hardened memberships match the held-out column more closely.
The link loads the sample. Run is still required.
Fuzzy C-Means on Wine (UCI wine recognition) (178 rows and 13 features) keeps a membership for every row (m=2.0). The published scores use the hardened memberships: 3 clusters, silhouette 0.285, adjusted Rand 0.897. K-Means on the same scaled rows uses 3 means, silhouette 0.285, adjusted Rand 0.897. Held-out agreement does not separate the hardened memberships from the means.
The link loads the sample. Run is still required.
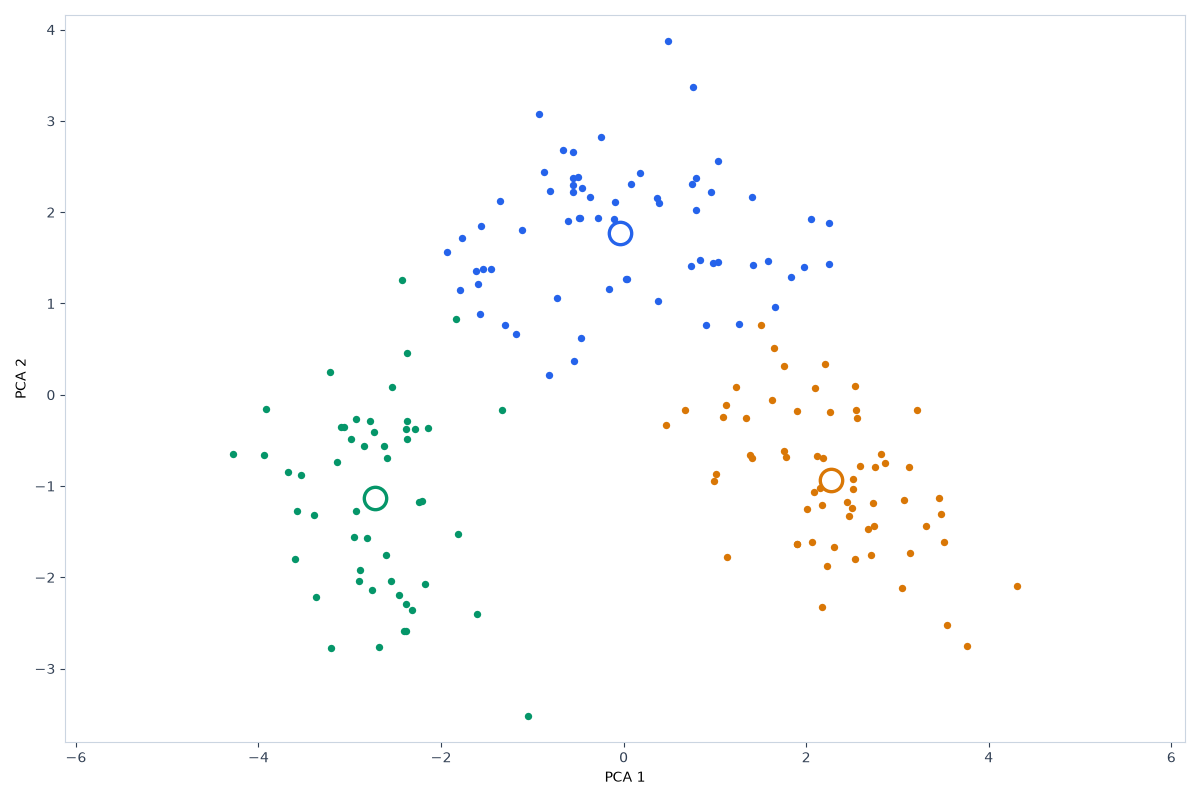
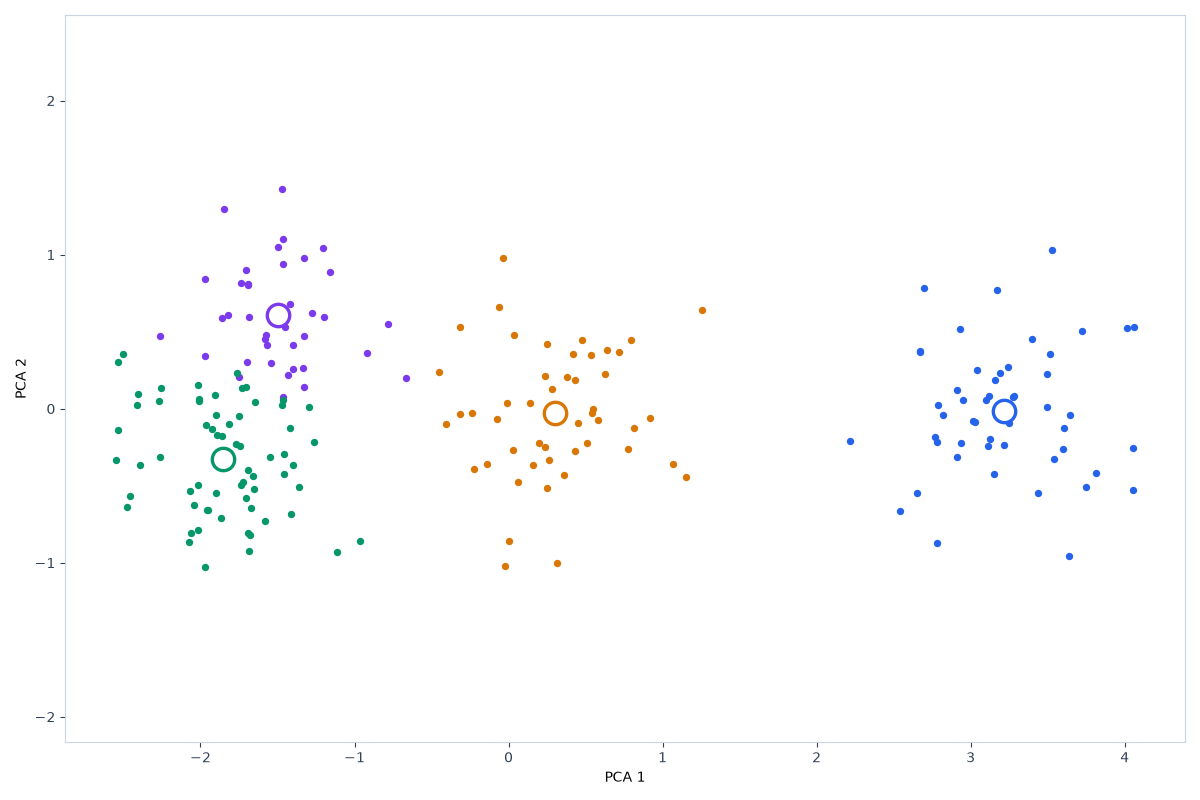
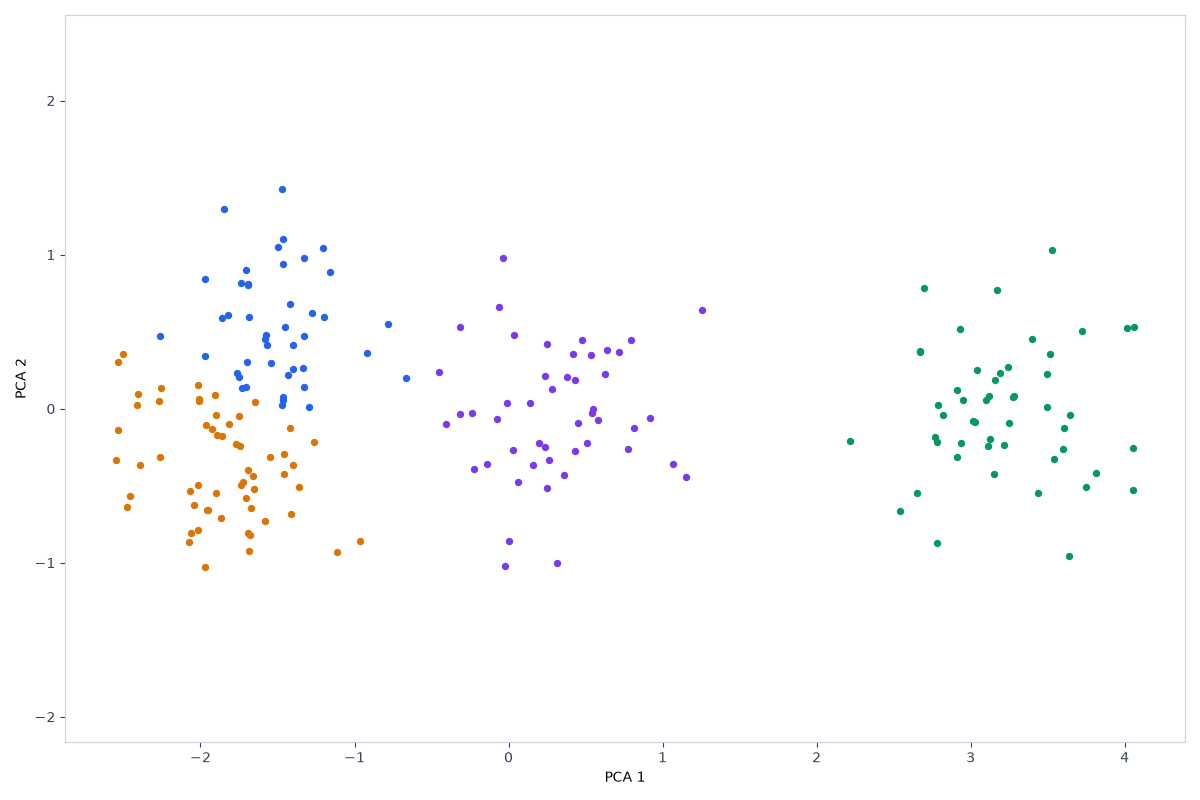
Fuzzy C-Means on Customer Segments (200 rows and 5 features) keeps a membership for every row (m=2.0). The published scores use the hardened memberships: 4 clusters, silhouette 0.364, adjusted Rand 0.794. K-Means on the same scaled rows uses 4 means, silhouette 0.368, adjusted Rand 0.763. The hardened memberships match the held-out column more closely.
The link loads the sample. Run is still required.
| Dataset | Algorithm | Clusters | Noise | Silhouette | Adjusted Rand |
|---|---|---|---|---|---|
| Iris Flowers | K-Means Clustering | 3 | 0 | 0.460 | 0.620 |
| Iris Flowers | Fuzzy C-Means Clustering | 3 | 0 | 0.458 | 0.630 |
| Wine (UCI wine recognition) | K-Means Clustering | 3 | 0 | 0.285 | 0.897 |
| Wine (UCI wine recognition) | Fuzzy C-Means Clustering | 3 | 0 | 0.285 | 0.897 |
| Customer Segments | K-Means Clustering | 4 | 0 | 0.368 | 0.763 |
| Customer Segments | Fuzzy C-Means Clustering | 4 | 0 | 0.364 | 0.794 |
K-Means assigns each row to the nearest mean. Fuzzy C-Means keeps a membership for every row, with m=2.0, and the published scores use the hardened memberships.
Method: StandardScaler, drop constant columns. Code version 3e4afc4b4352 (scripts/seo/build_explore_artifacts.py). scikit-learn 1.4.2. Seed 42. Both algorithms were fit on the same scaled table. Where a label column exists, it was held out of the fit and scored with adjusted Rand. Iris Flowers: UCI Machine Learning Repository, Iris (Fisher, 1936). License: CC BY 4.0. Wine (UCI wine recognition): UCI Machine Learning Repository, wine recognition. License: CC BY 4.0. Customer Segments: Synthetic customer records bundled with this site. License: Generated for demos; no external license.
Results computed, published, and last updated on 2026-11-02.
The comparison sentences are filled from these published runs by a fixed template, so the scores can be checked against the same datasets in the tool.
Maintainer: nikolaou1982.
Contact: nick1982100@gmail.com.