Results of this run
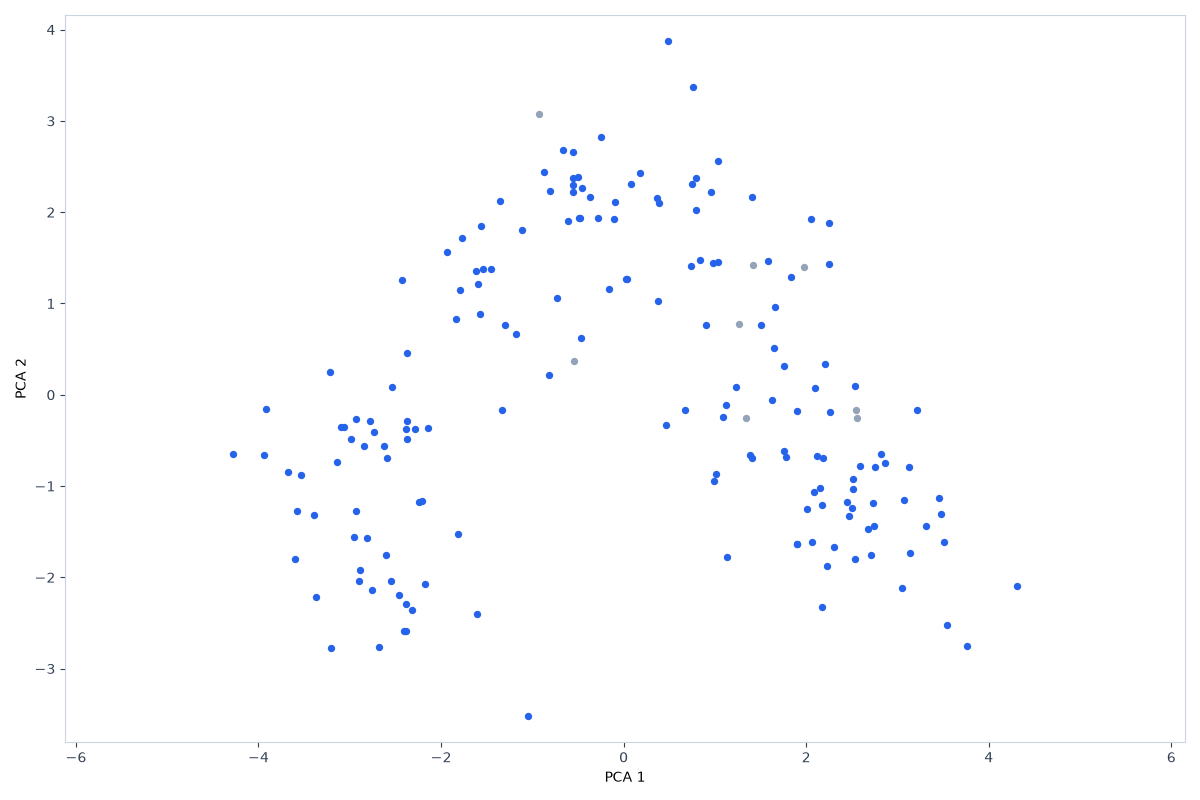
DBSCAN density on Wine (UCI wine recognition) uses eps 3.255357 and minSamples 5. Density silhouette is not defined (undefined when fewer than two dense regions). Density Calinski-Harabasz is not defined. Density Davies-Bouldin is not defined. Held-out wine_class versus dense regions: adjusted Rand not defined. 8 noise rows out of 178 failed the core-point rule. Dense region 0 on Wine (UCI wine recognition) holds 170 rows (proline 749.3 / od280/od315_of_diluted_wines 2.60). minSamples sweep: min_samples 3 yields 0.239 with 2 groups on Wine (UCI wine recognition); min_samples 5 yields not defined with 1 groups on Wine (UCI wine recognition); min_samples 8 yields not defined with 1 groups on Wine (UCI wine recognition). Density scatter keeps 55.4% via PCA.
| min_samples | Silhouette | Clusters |
|---|---|---|
| 3 | 0.239 | 2 |
| 5 | — | 1 |
| 8 | — | 1 |
from sklearn.cluster import DBSCAN
from sklearn.preprocessing import StandardScaler
Xs = StandardScaler().fit_transform(X)
labels = DBSCAN(eps=3.255357, min_samples=5).fit_predict(Xs)
Who, how, and why
Method: StandardScaler, drop constant columns. Code version 3e4afc4b4352 (scripts/seo/build_explore_artifacts.py). scikit-learn 1.4.2. Seed 42. Dataset source: UCI Machine Learning Repository, wine recognition. License: CC BY 4.0. The wine_class column was held out of the fit and used only for the adjusted Rand score.
Results computed on 2026-11-02.
The results paragraph is filled from these numbers by a fixed template in the site code, so the scores can be checked against the same dataset in the tool.
Maintainer: nikolaou1982.
Contact: nick1982100@gmail.com.