Results of this run
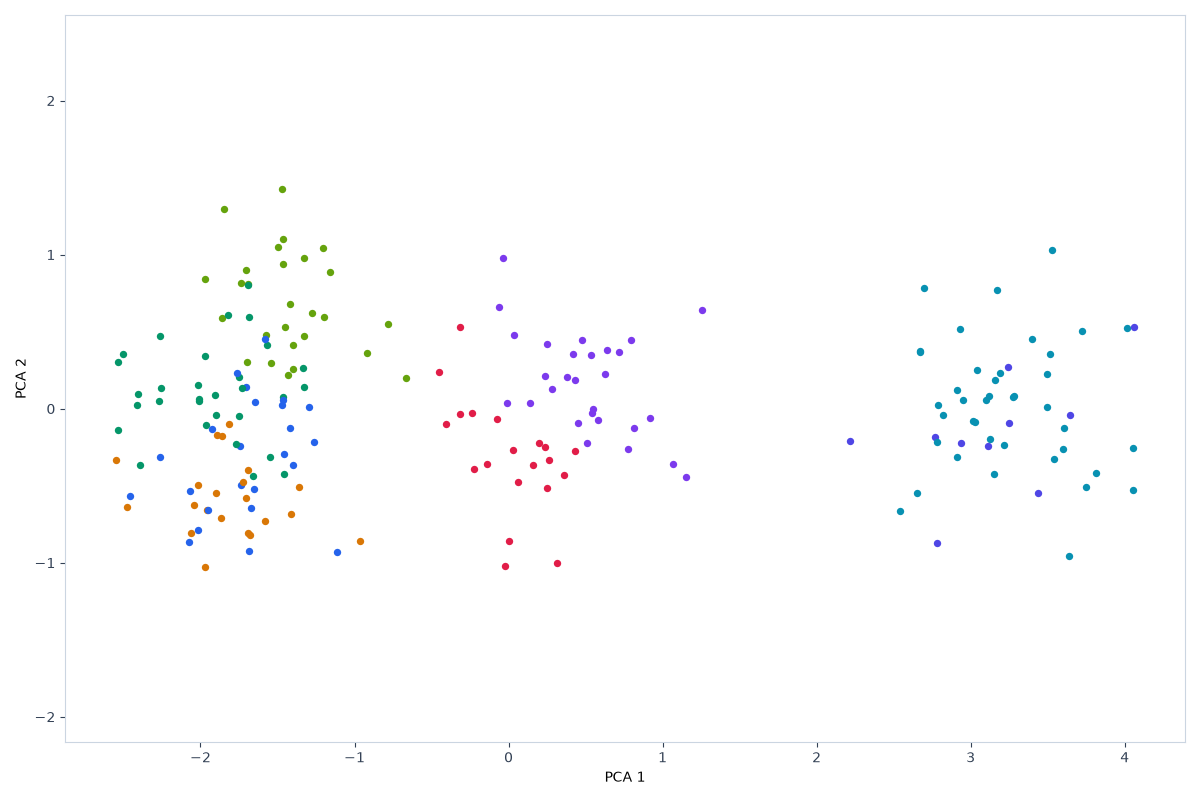
Affinity Propagation on Customer Segments (damping 0.7) elects exemplar rows instead of taking k as input. Exemplar silhouette is 0.178, exemplar Calinski-Harabasz is 200.4, exemplar Davies-Bouldin is 1.810. Held-out segment versus exemplars: adjusted Rand 0.525. 0 noise rows out of 200 without an exemplar. Exemplar group 0 on Customer Segments holds 24 rows (annual_income 36617.1 / avg_spend 667.7). Exemplar group 1 on Customer Segments holds 30 rows (annual_income 38369.8 / avg_spend 725.3). Exemplar group 2 on Customer Segments holds 21 rows (annual_income 24370.8 / avg_spend 737.3). Exemplar group 3 on Customer Segments holds 28 rows (annual_income 62152.1 / avg_spend 1688.4). Exemplar group 4 on Customer Segments holds 20 rows (annual_income 47632.0 / avg_spend 1618.7). Exemplar group 5 on Customer Segments holds 40 rows (annual_income 79677.0 / avg_spend 3094.3). Exemplar group 6 on Customer Segments holds 10 rows (annual_income 73298.0 / avg_spend 2390.5). Exemplar group 7 on Customer Segments holds 27 rows (annual_income 48533.3 / avg_spend 581.5). Damping path: damping 0.5 elects 0.173 with 8 groups on Customer Segments; damping 0.7 elects 0.178 with 8 groups on Customer Segments; damping 0.9 elects 0.178 with 8 groups on Customer Segments. Exemplar scatter keeps 90.5%.
| damping | Silhouette | Clusters |
|---|---|---|
| 0.5 | 0.173 | 8 |
| 0.7 | 0.178 | 8 |
| 0.9 | 0.178 | 8 |
from sklearn.cluster import AffinityPropagation
from sklearn.preprocessing import StandardScaler
Xs = StandardScaler().fit_transform(X)
labels = AffinityPropagation(damping=0.7, random_state=42).fit_predict(Xs)
Who, how, and why
Method: StandardScaler, drop constant columns. Code version 3e4afc4b4352 (scripts/seo/build_explore_artifacts.py). scikit-learn 1.4.2. Seed 42. Dataset source: Synthetic customer records bundled with this site. License: Generated for demos; no external license. The segment column was held out of the fit and used only for the adjusted Rand score.
Results computed on 2026-11-02.
The results paragraph is filled from these numbers by a fixed template in the site code, so the scores can be checked against the same dataset in the tool.
Maintainer: nikolaou1982.
Contact: nick1982100@gmail.com.